AI Crawler Policy Operations: Separating Cloudflare and OpenAI Bots for GEO
A GEO operating guide for deciding which AI bots to allow, restrict, or monitor as AI search, agent, and training crawlers become separate traffic classes.
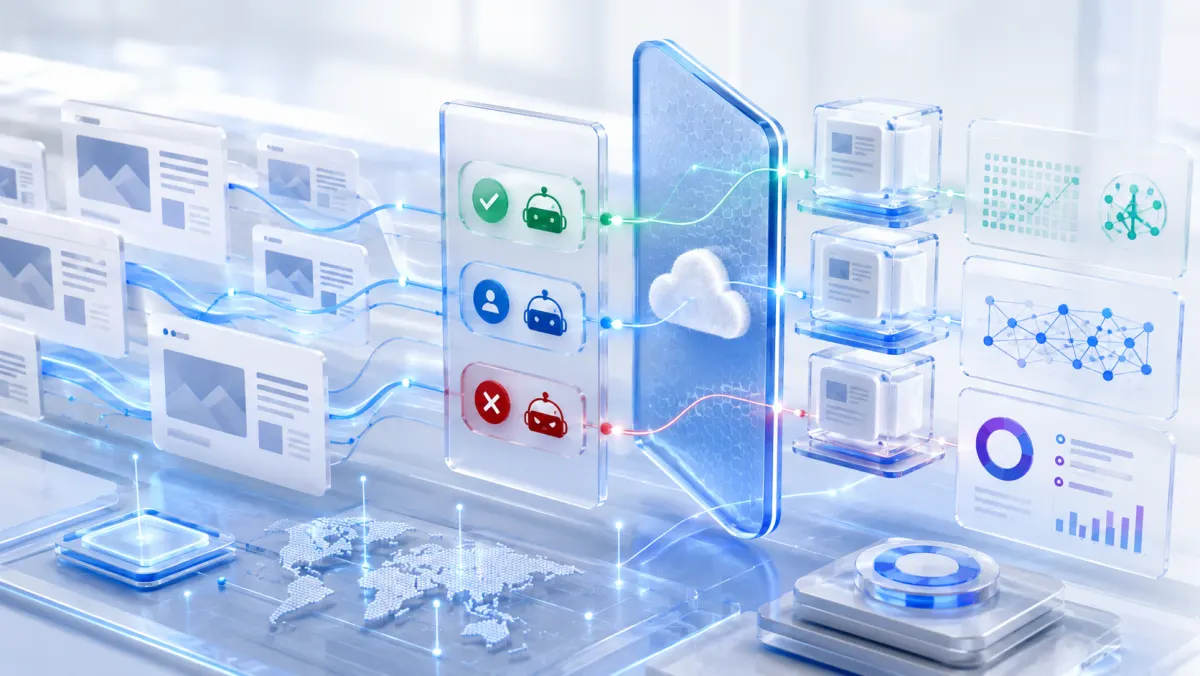
AI crawler policy can no longer be reduced to allow or block. Teams need to separate crawlers that support search visibility, agents acting on behalf of users, and training crawlers, then manage discoverability and content protection together.
- Cloudflare introduced an AI traffic taxonomy of Search, Agent, and Training in July 2026 and announced September 15, 2026 defaults that keep Search allowed while blocking Training and Agent traffic on ad pages for new domains.
- OpenAI separates OAI-SearchBot, OAI-AdsBot, and GPTBot. To appear in ChatGPT search, teams should allow OAI-SearchBot while managing GPTBot separately when training use needs limits.
- GEO operations should connect robots.txt, CDN rules, sitemap and RSS, citation candidate URLs, crawler logs, and article-to-pricing movement.
Cloudflare describes AI traffic through Search, Agent, and Training use cases and argues that multi-purpose crawlers should be tracked by all relevant purposes.
OpenAI documentation describes OAI-SearchBot as search-related and GPTBot as crawling content that may be used for training foundation models.
Google says eligibility for AI Overviews or AI Mode supporting links requires indexed pages that can show snippets, with crawling allowed by robots.txt, CDN, and hosting infrastructure.
1. Treating all AI bots as one group can block GEO opportunity
In the past, many sites only needed to distinguish search-engine bots from malicious bots. That is no longer enough. In July 2026, Cloudflare described AI traffic through three use cases: Search, Agent, and Training. Search collects or indexes content to answer questions later, Agent traffic acts in real time on behalf of a user, and Training takes content to train or fine-tune models.
The riskiest GEO choice is blocking every AI bot. Blocking training use may be reasonable, but if search-oriented bots are blocked too, the site can also lose opportunities to appear in ChatGPT search, AI answer engines, and other discovery surfaces. Opening everything creates the opposite risk: proprietary content and ad landing pages may become too easy to reuse without control.
Policy should therefore start from crawler purpose, not only crawler name. The same company may operate separate systems for search, ad review, user-triggered fetching, and model training. Purpose-based rules let a team balance visibility and protection.
- Search: usually a candidate for allow because it can support AI answer citation and discovery.
- Agent: review scope and rate limits separately because it acts on behalf of users.
- Training: manage separately when model-training use should be restricted.
- Ads verification: log and review separately from general search crawlers.
2. OpenAI bots require separate search and training decisions
OpenAI documentation separates the purposes of OAI-SearchBot and GPTBot. OAI-SearchBot is used for surfacing websites in ChatGPT search features. GPTBot crawls content that may be used for training generative AI foundation models. Managing both with one rule makes it difficult to keep desired search visibility while limiting undesired training use.
A practical policy is straightforward. If the site should be discoverable in ChatGPT search, allow OAI-SearchBot. If training use should be limited, manage GPTBot separately. If ads are part of the channel mix, OAI-AdsBot also belongs in its own bucket because it is used to review landing pages submitted for ChatGPT ads.
This distinction matters for GEO diagnostics. A site that blocks search bots and then asks why it is not visible in AI search is looking at the wrong problem. A site that allows training bots and calls that visibility is also using the wrong metric. Purpose, policy, logs, and citation-candidate status need to be reviewed together.
- OAI-SearchBot: allow when ChatGPT search visibility is desired.
- GPTBot: evaluate separate Disallow rules when training use should be restricted.
- OAI-AdsBot: connect to ad landing-page review logs.
- ChatGPT-User: treat as user-triggered access, not as the search opt-out control.
3. Cloudflare policy extends beyond robots.txt
Robots.txt still matters, but it is not enough. Google explains that AI feature eligibility depends on crawling being allowed not only by robots.txt but also by CDN and hosting infrastructure. A CDN-level block can prevent crawler access even when robots.txt says allow.
Cloudflare introduced Pay Per Crawl in 2025 as a way for site owners to choose Allow, Charge, or Block for crawlers. In 2026, Cloudflare expanded the discussion toward purpose-based Search, Agent, and Training controls, Crawler Hints, and Pay Per Use experiments. The important shift is from blocking everything to understanding which access creates value exchange.
When GEO Gateway runs behind Cloudflare, at least three layers need review: robots.txt user-agent rules, Cloudflare AI Bot or WAF rules, and the application HTML plus sitemap and RSS that crawlers actually receive. If one layer is misaligned, search crawlers may fail to discover URLs or may not receive enough evidence to treat them as AI answer candidates.
- Align robots.txt and Cloudflare AI traffic settings under the same purpose taxonomy.
- Allow Search-purpose crawlers for public landing pages and guides that need visibility.
- Restrict Agent and Training access separately for ad pages, billing, and private dashboards.
- After policy changes, inspect logs for 200, 403, and 402 responses.
4. The GEO dashboard should store policy and conversion data together
AI crawler policy should not end as a security setting. Teams need to connect which bot accessed which URL, whether that URL became a search or AI answer candidate, and whether users moved from the article to featured guides or pricing.
If OAI-SearchBot is allowed but no blog URLs are requested, review sitemap, RSS, internal links, DNS, and CDN caching. If requests exist but there is no search traffic or citation signal, review article structure, body evidence, schema, and title. If search traffic exists but conversion movement is weak, review CTA placement and pricing explanation.
The GEO goal is not to maximize every AI access. Open the access needed for search visibility, limit access that creates training or automation risk, and measure whether the policy leads to real traffic and conversion movement. That standard keeps a blog useful on Cloudflare and Railway without turning crawler policy into guesswork.
- Record crawler access logs and robots or CDN policy changes by URL.
- After search crawler access, track sitemap reflection, citation candidates, and non-brand impressions.
- Separate article-to-guide, article-to-pricing, and article-to-7-day-trial events.
- Treat expanded bot access as a measurable operating experiment, not a loose security exception.
Turn this checklist into your first AI View.
For 7 days, test AI View creation, AI request monitoring, and traffic and conversion tracking inside GEO Gateway.
Start your 7-day free trial